Every few years a neural network architecture comes along that resets expectations. Convolutional networks did it for images. Recurrent networks did it for sequences. Then, in 2017, transformers did it for pretty much everything. And they are the reason the AI you use today can hold a conversation. If you have ever wondered how these three actually differ, this is the clear version.
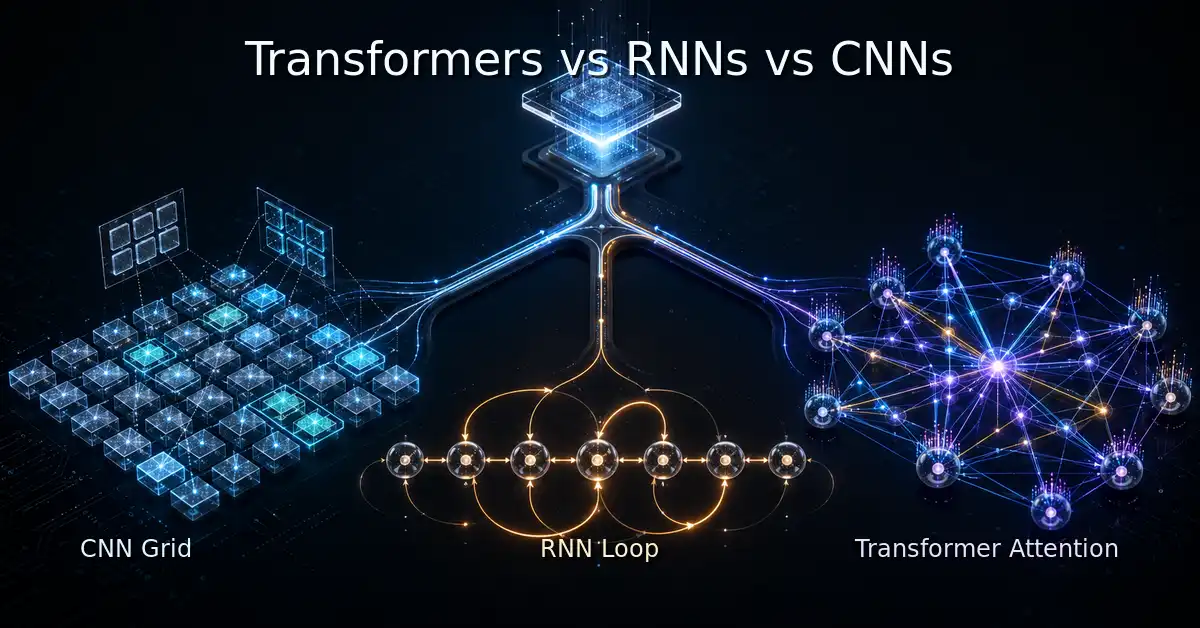
The one-line summary: CNNs are built to spot local patterns in grid-like data, RNNs walk through a sequence one step at a time, and transformers look at the whole sequence at once using attention. That last trick is what changed the game.
Side by side
| CNN | RNN | Transformer | |
|---|---|---|---|
| Best suited to | Images, grids | Ordered sequences | Sequences (and almost anything) |
| How it reads data | Local, in parallel | Step by step | All at once, in parallel |
| Long-range links | Limited | Weak over distance | Excellent |
| Training speed | Fast | Slow | Fast (parallelizable) |
| Famously powers | Computer vision | Older NLP, speech | Large language models |
CNNs: pattern detectors for grids
A convolutional neural network slides small filters across an image, each one learning to react to a particular feature: an edge here, a texture there, later a whole eye or wheel. Because those filters scan every part of the image independently, a CNN is fast and naturally parallel. It is brilliant at anything with a spatial grid: photos, medical scans, even spectrograms of audio. What it is not built for is understanding order over long distances, which is exactly where sequences come in.
RNNs: reading in order, with a catch
A recurrent neural network processes a sequence one element at a time, carrying a hidden state forward as a kind of running memory. Conceptually it is a lovely fit for language, where word order carries meaning. The drawback is twofold. First, that step-by-step design cannot be parallelized easily, step ten has to wait for step nine, so training is slow. Second, the memory tends to fade over long spans. LSTMs and GRUs patched the memory problem, but the sequential bottleneck remained. That bottleneck is the opening transformers walked through.
Transformers: attention changes everything
The transformer threw out recurrence altogether. Instead of walking a sequence step by step, it looks at every position at the same time and uses a mechanism called self-attention to let each word weigh its relationship to every other word directly. The word “it” in a sentence can look straight back at the noun it refers to, however far away that noun sits, in a single operation.
Two consequences fell out of that design, and both mattered greatly. Because everything is processed together, transformers train in parallel and scale beautifully on modern hardware. And because attention connects any two positions directly, long-range relationships stop being a struggle. Put those together and you get models that can be trained on staggering amounts of text, which is precisely what powers today’s large language models.
The evidence behind the shift
The transformer was introduced in “Attention Is All You Need” (Vaswani et al., 2017), an architecture based solely on attention mechanisms that dispenses with recurrence and convolutions entirely. On the WMT 2014 English-to-German translation task it reached 28.4 BLEU, improving on the best earlier results, including ensembles, by more than 2 BLEU. On English-to-French it set a new single-model state of the art of 41.8 BLEU after 3.5 days of training on eight GPUs, which the authors describe as a small fraction of the training cost of the best earlier models. Attention itself was not new. In 2014, Bahdanau, Cho and Bengio had added a mechanism that let a translation model learn to align with the relevant parts of the source sentence. The 2017 paper showed attention could stand on its own.
The same idea then crossed into vision. Dosovitskiy and colleagues (2020) showed that a pure transformer applied directly to sequences of image patches, the Vision Transformer, can perform very well on image classification. When pre-trained on large amounts of data, it attained excellent results compared with state-of-the-art convolutional networks while requiring substantially fewer computational resources to train. That is a result about large-scale pre-training, not a sign that CNNs are obsolete, and it fits the point below that the right architecture depends on data and hardware.
CNNs have a foundational result of their own. LeCun, Bottou, Bengio and Haffner (1998) described gradient-based learning applied to document recognition, the line of work behind convolutional networks for handwritten character recognition. For a wider comparison, see our guide to machine learning, deep learning and neural networks.
Do CNNs and RNNs still matter?
They do, and it is worth being clear about why. CNNs remain the workhorse of computer vision and run efficiently on small devices where a full transformer would be wasteful. RNNs, LSTMs and GRUs are still a sensible choice for lightweight time-series and streaming tasks. “Transformers won” is true for large-scale language, but it does not mean the other two are museum pieces. Choosing an architecture is still about matching the tool to the data.
If you want to see how these fit alongside the other major designs, including graph neural networks, our ANN vs CNN vs RNN vs GNN cheat sheet maps the whole family in one place.
Key takeaways
- Transformers replaced recurrence with attention and trained faster in parallel while improving translation quality.
- Attention was developed for RNN-based translation first, then shown to work on its own.
- Vision transformers can match convolutional networks after large-scale pre-training, but CNNs remain efficient for many vision tasks.
Sources
- Vaswani et al., “Attention Is All You Need”, 2017.
- Bahdanau, Cho and Bengio, “Neural Machine Translation by Jointly Learning to Align and Translate”, 2014.
- Dosovitskiy et al., “An Image is Worth 16×16 Words: Transformers for Image Recognition at Scale”, 2020.
- LeCun et al., “Gradient-based learning applied to document recognition”, Proceedings of the IEEE, 1998.
How we checked this: we compared the figures and findings above with each paper’s published abstract and record. Results are specific to the tasks and datasets those papers used.